- contact@insightairesolve.com
Agentic L1 support and incident resolution. Part of the InsightLake enterprise AI suite by VerticalServe, on the same InsightWorker engine as InsightTestBench and InsightStudio.
VerticalServe runs data platforms and AI systems for enterprises — and the on-call that comes with them. The pattern was the same everywhere: the alert fires, an engineer opens ten tools, follows a runbook that is half right, and the reason for the fix never gets written down. The next incident starts from zero.
We had already built InsightWorker, an agent engine with tools for Airflow, databases, Jira, HTTP and shells, and InsightTestBench, which uses it to run QA plans. Pointing the same engine at incident triage was the obvious step: give it the runbook as structured steps, the credentials for the monitoring stack, and the alert as context, and let it do the L1 work before a human is paged for L2.
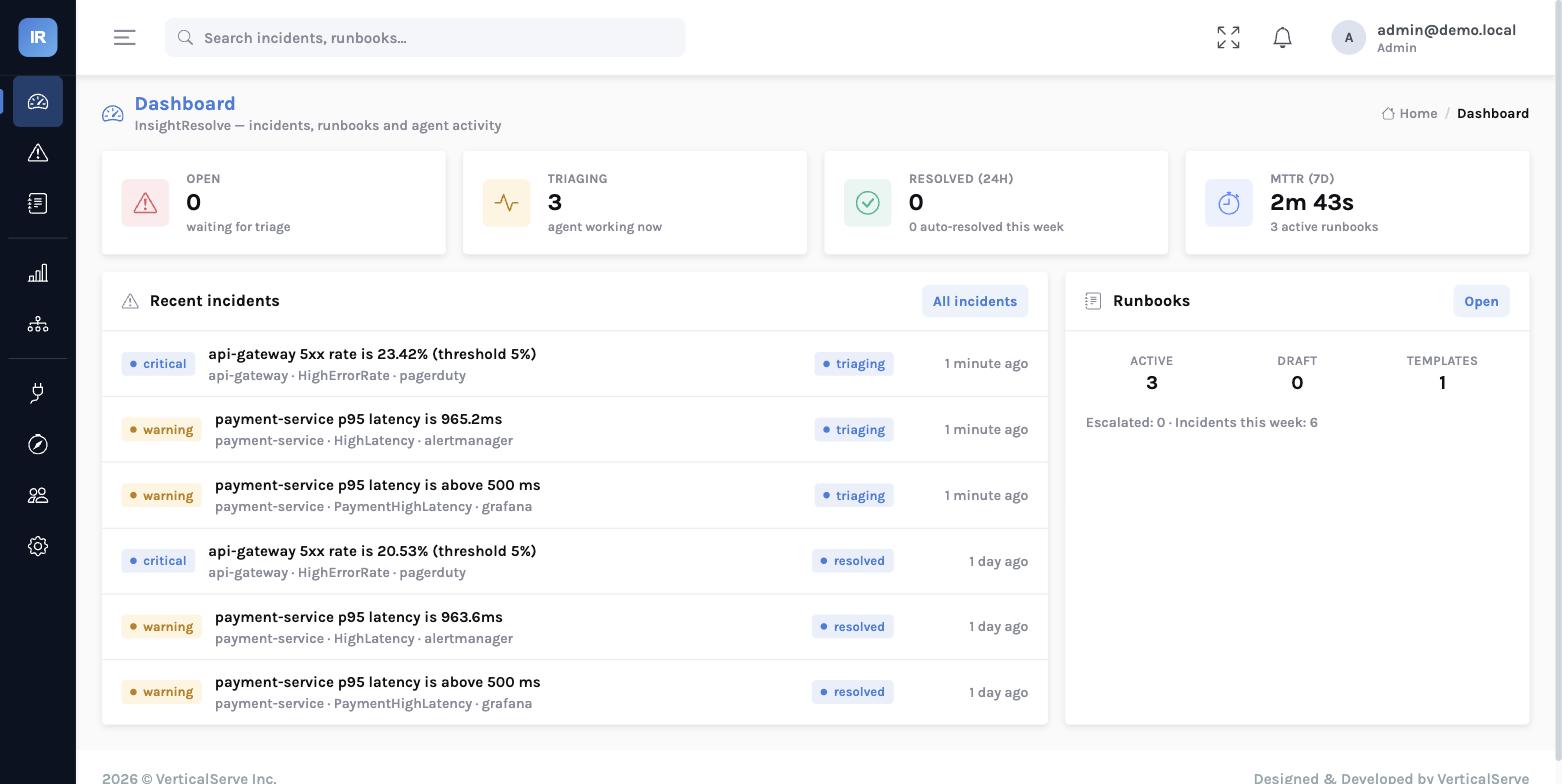
InsightResolve is that product: webhooks in, runbooks executed, root cause written down, and every execution feeding back into how good each runbook is. Classification before remediation — the agent decides what happened and why; anything that changes production waits for a person to say yes.
Shared identity, connection registry, audit trail, Postgres and SSE. What differs is the domain model, the screens and the skills the agent loads.
The README that started the product listed them; the product keeps them.
Steps, conditions, variables and match rules are rows. The UI does targeted edits; versions diff cleanly; searching “every runbook that queries Prometheus” is a WHERE clause.
Phase one answers “what happened and why”. Restarts and scaling come later, behind explicit human approval gates, never as a surprise.
Incidents arrive by push, in real time. Polling exists as a fallback; the primary trigger is the page itself.
Integration credentials are sealed in the registry and handed to the worker at dispatch time. The worker never persists them; logs show secret names, not values.
Your cloud, your VPC, your model provider. Incidents, evidence and RCAs do not leave your perimeter.
Which runbook version ran, which steps, what each returned, what the classifier concluded and how confident it was — on the incident, forever.
Arrive at incidents with context gathered and a first diagnosis done.
Runbook management, integration health, MTTR tracking, coverage gaps.
Airflow and dbt pipeline failures triaged, retried and ticketed with logs attached.
Shift summaries, incident metrics, false-positive rates, trend analysis.